Workflows
Every workflow FlixML ships, grouped by what goes in and what comes out. Each one runs on your own GPU — the VRAM figure is what it actually needs, measured on consumer cards, not a vendor minimum. 17 workflows across 6 task types.
Text → Image
FLUX.2 Klein Image
Text-to-image with FLUX.2 Klein 4B. High-fidelity stills from a prompt, with two optional LoRA slots.
flux2_klein8 GB VRAMLoRA
Krea 2 Turbo
Krea 2 Turbo makes an image from a prompt in 8 steps, 1K to 2K. Krea 2 Community License: https://www.krea.ai/krea-2-licensing
krea2_turbo12 GB VRAMLoRA
Qwen-Image 2.1
Qwen-Image 2.1 makes an image from a prompt. To edit from reference images, use qwen_image_21_edit. Qwen Research License: non-commercial use only.
qwen_image_2112 GB VRAM
SDXL Image
Text-to-image with an SDXL checkpoint or any SDXL finetune, with up to two LoRAs and an optional face-detail pass. General-purpose still generation from a prompt — no source image.
sdxl_base8 GB VRAMLoRA
Text Logo / Wordmark
Typeset exact text as a logo/wordmark using a real TTF font (ComfyUI AddLabel node) — NOT diffusion. Use this whenever the output must spell an exact string (a handle, brand, wordmark) that diffusion models garble. Renders instantly, GPU-light, lands in the gallery like any generation.
text_logo1 GB VRAMImage → Image
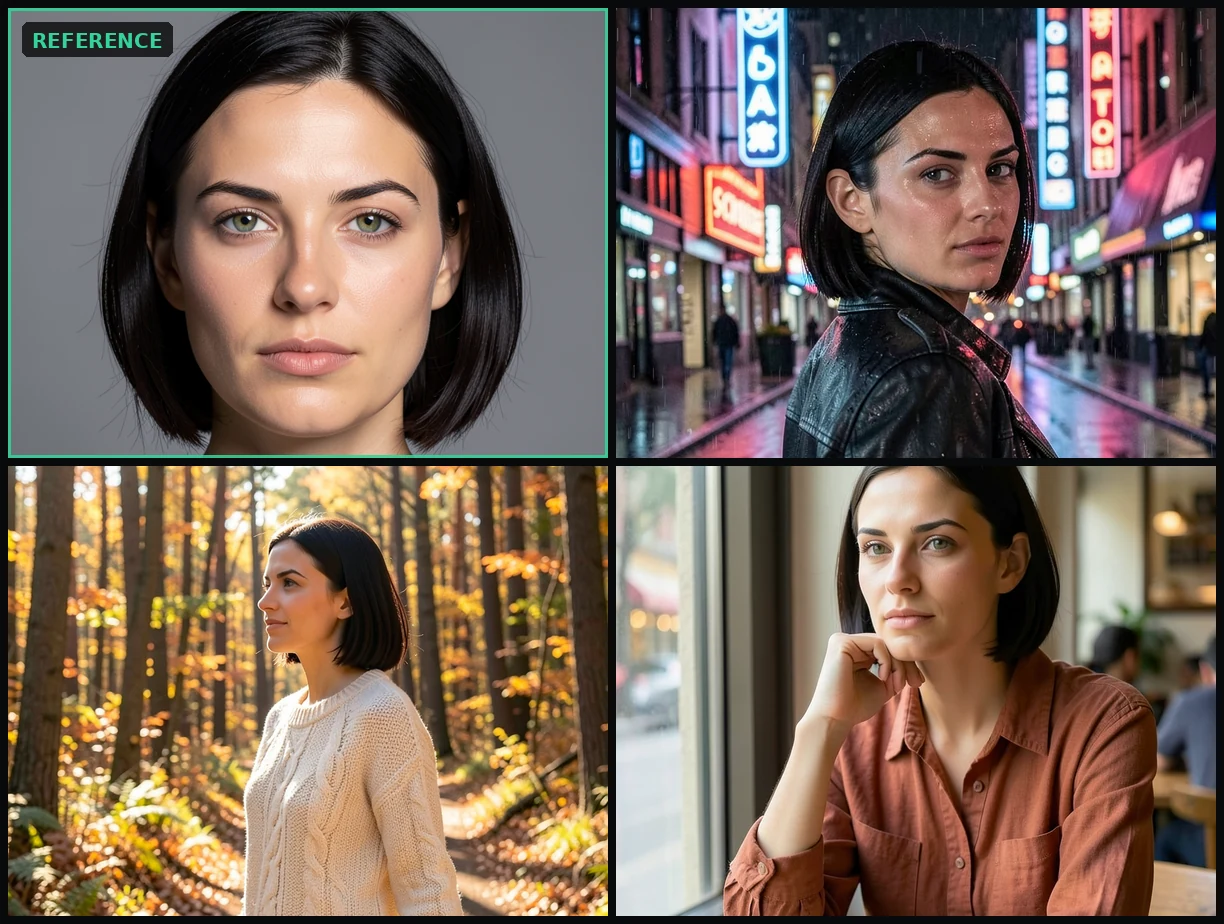
FLUX.2 Klein Reference Edit
Generate a new image from a reference image and a plain-English instruction. FLUX.2 Klein 4B reads the reference as conditioning and samples a fresh frame, so unlike img2img it can change pose, wardrobe and setting while holding the subject's identity. Say what changes and what stays.
flux2_klein_edit8 GB VRAMLoRAQwen-Image 2.1 Reference Edit
Qwen-Image 2.1 makes a new image from one to three reference images and a plain-English instruction, such as putting the shirt from <image2> on the person in <image1>. Say what changes and what stays. Qwen Research License: non-commercial use only.
qwen_image_21_edit12 GB VRAM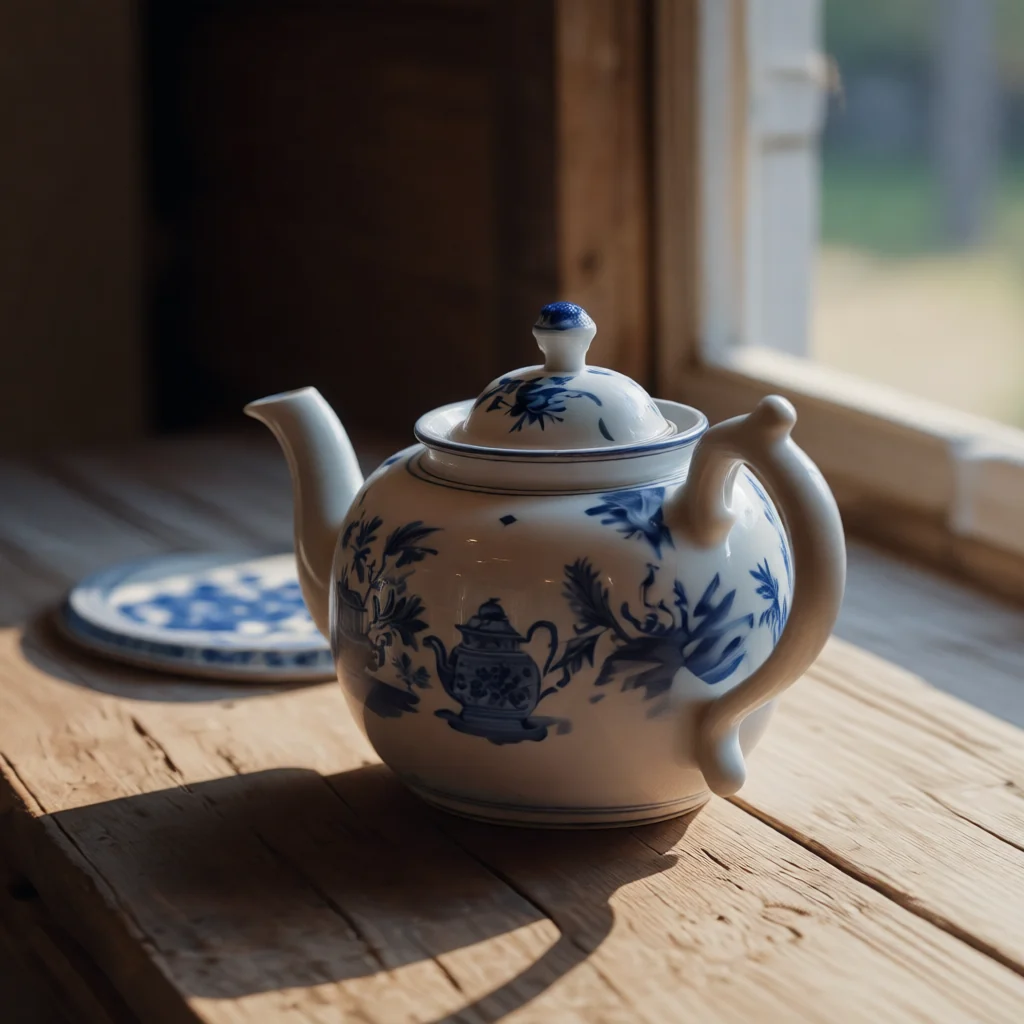
Qwen Multi-Angle (re-angle a still)
Re-shoot an existing image of the same subject from a new camera angle. Qwen-Image-Edit-2511 + multi-angle LoRA holds identity, clothing, and lighting while changing the camera viewpoint. Produces a sibling of the source still at a different angle.
qwen_multiangle12 GB VRAMQwen Pose/Position Edit (instruction)
Edit an existing image from a plain-English instruction — change a subject's pose, position, or what they're doing while holding their identity, clothing, the room, and lighting. Powered by Qwen-Image-Edit-2511; the source image is the reference (no LoRA).
qwen_pose_edit12 GB VRAM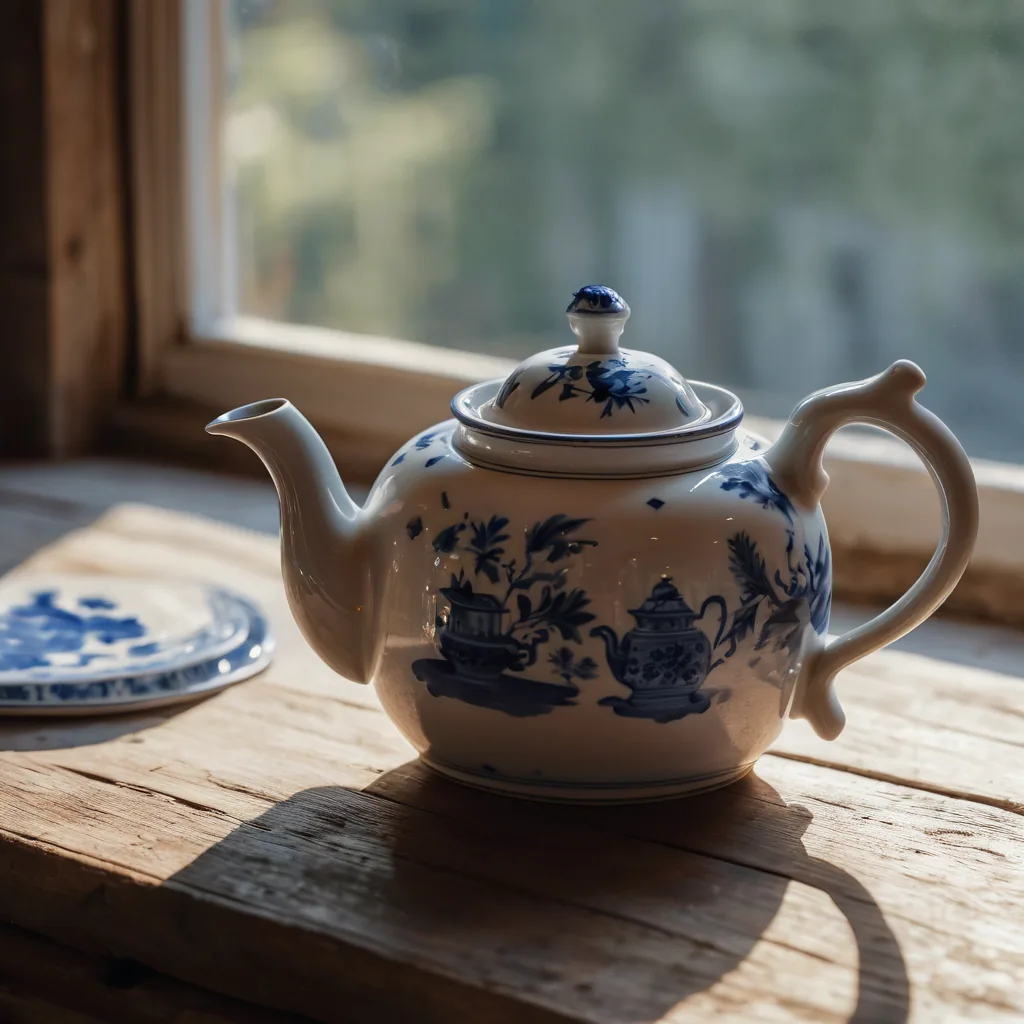
SDXL Image-to-Image
Generate SDXL image variations from a source image using prompt guidance and denoise strength
sdxl_img2img8 GB VRAMText → Video
Image → Video
InfiniteTalk Image-to-Video (lip-sync)
Audio-driven talking-head. Animates a still image to lip-sync a voice line (Wan 2.1 I2V backbone + InfiniteTalk/MultiTalk). Talking-head motion only, not big body motion.
infinitetalk_i2v12 GB VRAMWan 2.2 Image-to-Video
Image-to-video with Wan 2.2 — animate a still into a clip, with a motion prompt driving the movement. Identity and scene come from the source image. Past 81 frames the clip is sampled in overlapping context windows and fused, so one action carries on as ONE clip — use a longer length instead of taking a clip's last frame and animating it again, which hands the model a still and restarts the motion from rest.
wan22_i2v12 GB VRAMLoRAVideo → Video
GVHMR Motion Capture
Pulls one person's body motion out of a video with GVHMR. The pack author's two bundled workflows as shipped: GVHMR.json (clip + mask video of the same clip, person white on black → GVHMRInference → SMPLViewer) and smpl_to_bvh_pipeline.json (SMPLtoBVH → BVHViewer), joined where the author's tooltip says: SMPLtoBVH reads GVHMRInference's npz_path. Writes <filename_prefix>_motion.bvh, a GLB of the motion (the pack's SMPLToGLB) and smpl_params_*.npz to the node's output folder, plus a preview video for the gallery: HY-Motion's HYMotionPreview2D draws the captured skeleton from the front (azimuth 90), at the clip's fps, up to 500 frames. Licence: GVHMR and its SMPL body model are non-commercial, research and education only. Needs the ComfyUI-MotionCapture (github.com/PozzettiAndrea/ComfyUI-MotionCapture) and ComfyUI-HyMotion (github.com/PozzettiAndrea/ComfyUI-HyMotion) node packs.
gvhmr_mocap8 GB VRAMInfiniteTalk Video-to-Video (motion + lip-sync)
Audio-driven lip-sync applied on top of a driving motion clip. Loads a source video (e.g. a subject dancing/twirling from a t2v/i2v run), encodes its motion, and re-samples it to lip-sync a voice line while preserving the body motion (Wan 2.1 I2V backbone + InfiniteTalk/MultiTalk). Use this instead of infinitetalk_i2v when you want real body motion, not just a talking head.
infinitetalk_v2v12 GB VRAMSAM 3 Video Mask
Cuts one subject out of a video as a mask: the subject white, everything else black, same frame count and frame rate as the clip. SAM 3 finds what the prompt names and tracks it through every frame. For motion-capture nodes that take a person mask video alongside the clip. Uses ComfyUI's core SAM 3 nodes, the same tracking step as its SAM 3D Body template. SAM License: https://github.com/facebookresearch/sam3/blob/main/LICENSE
sam3_video_mask8 GB VRAMText → Speech
These are the workflows in the public repo. Your own install can carry more — anything you drop into workflows/local/ is listed byGET /api/workflows on your install and never here. Setting one up is covered in the workflow docs.