SDXL Base Image
Text → ImageText-to-image with an SDXL checkpoint. General-purpose still generation from a prompt — no character LoRA, no source image.
sdxl_base8 GB VRAM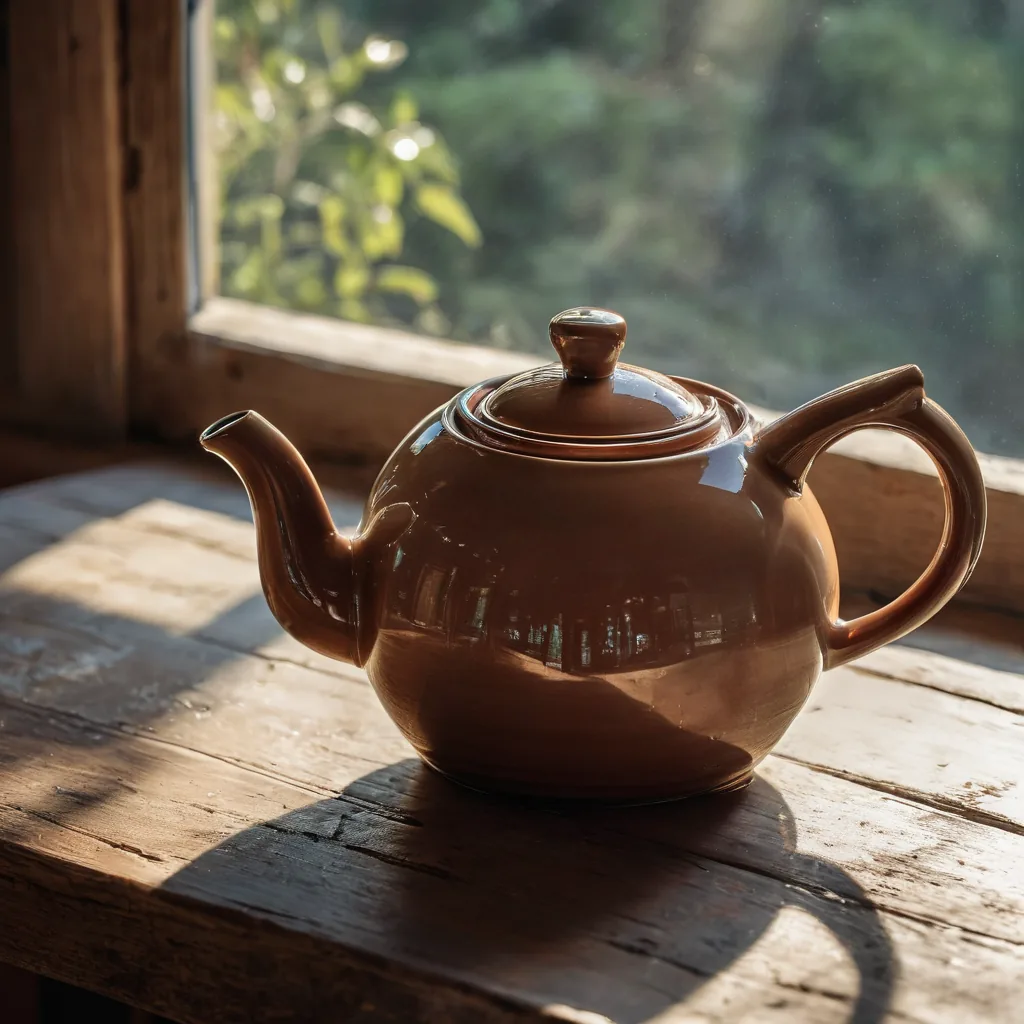
sdxl_base on our own hardware. Prompt: “a glazed ceramic teapot on a wooden table beside a window, morning light, still life photograph”Calling it
FlixML has no generate button: you tell your agent what you want and it calls the API on your install. The id is what names this workflow.
POST /api/image/generate
{
  "workflow": "sdxl_base",
  "prompt": 0,
  "checkpoint": 0
}
Parameters
promptstringrequiredComma-separated tags and short phrases, the way SDXL's training captions were written. A sentence still parses — it does not fail — but every article and preposition spends part of the same budget, so tags buy more control per token. Order is weight: subject, appearance, clothing, pose, setting, lighting, then medium and quality. 'young woman, short white hair, black leather jacket, standing in a rain-wet alley, neon signs, night, shallow depth of field, photorealistic, sharp focus'. Push or pull one term with `(term:1.2)` or `(term:0.8)`; bare `(term)` is 1.1. Keep it near 75 tokens — CLIP encodes the rest in a later chunk where it pulls less. Match the checkpoint: one trained on booru tags wants booru tags, one merged for realism wants photographic ones, and its model page is the authority on any trigger or quality tags it expects.
checkpointstringrequiredCheckpoint model filename discovered from the local ComfyUI node or supplied by the caller
negative_promptstringdefault What to steer away from, same tag syntax. SDXL uses this — unlike FLUX.2, which has no negative and needs the positive to say 'sharp focus' instead. Start with the defects you actually see rather than a stock wall of tags: 'blurry, low quality, extra fingers, watermark, text'. An oversized negative eats guidance and flattens the image.
widthintegerdefault 832heightintegerdefault 1216seedintegerdefault 42stepsintegerdefault 40cfgfloatdefault 5samplerstringdefault dpmpp_2mschedulerstringdefault karrasYour install is the source of truth: GET /api/workflows returns these parameters as they are on your machine.
Same input, different job
FLUX.2 dev + LoRA Image
Text-to-image with FLUX.2 plus one or more trained character LoRAs — a consistent identity rendered at high fidelity from a prompt.
FLUX.2 Klein Image
Text-to-image with FLUX.2 Klein 4B. High-fidelity stills from a prompt, with two optional LoRA slots.
SDXL + LoRA Image
Text-to-image with an SDXL checkpoint plus a character/style LoRA — a consistent trained identity or style rendered from a prompt.
Text Logo / Wordmark
Typeset exact text as a logo/wordmark using a real TTF font (ComfyUI AddLabel node) — NOT diffusion. Use this whenever the output must spell an exact string (a handle, brand, wordmark) that diffusion models garble. Renders instantly, GPU-light, lands in the gallery like any generation.